
What should I do about common server failures? Quick troubleshooting and handling guide
Time: 2026-09-29
Editor: USTAT.COM
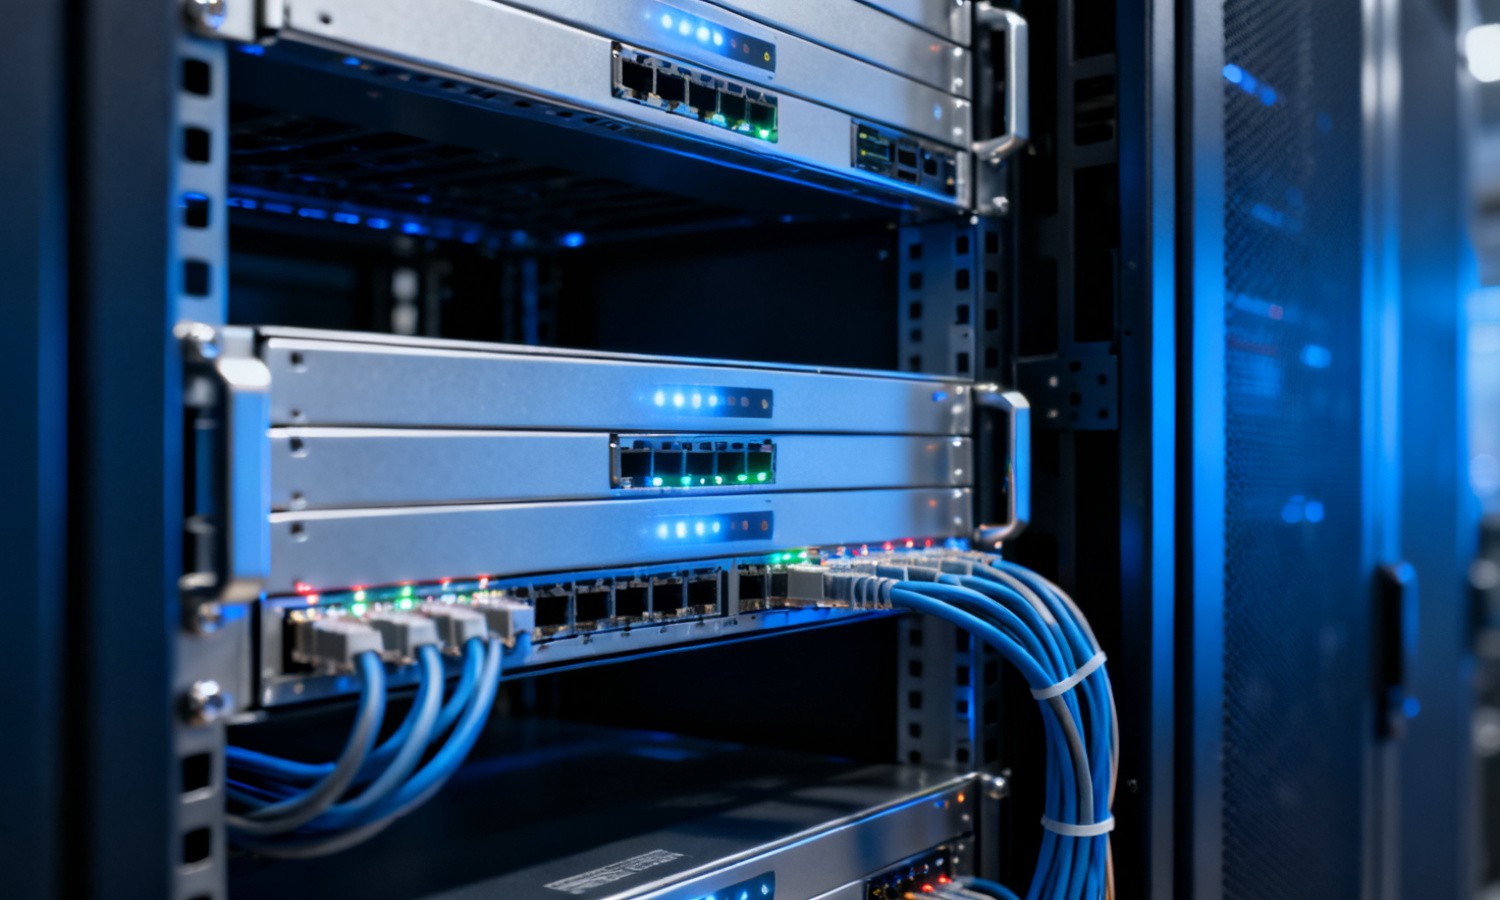
in the system of enterprise digital operation, the server is the key carrier that carries the business system and stores the core data. Once a failure occurs, it will affect the office efficiency at best, and cause business interruption and data loss at worst, resulting in incalculable losses. However, during the operation of the server, hardware loss, system vulnerabilities, network fluctuations and other factors may cause various problems. Many operation and maintenance personnel are often caught in a dilemma in the face of failures. This article will go from the basic arrangement to the deep processing, and help you disassemble the troubleshooting logic and solutions of common server failures to help quickly restore the normal operation of the server.
First, how to troubleshoot the server basic hardware failure?
hardware failure is one of the most common types of server problems, most of the initial failures are related to hardware connection or loss, and prioritizing hardware can quickly reduce the scope of failure.
1, physical connection and visual inspection
first check whether the power connection of the server is firm, confirm that the power cord and socket, the server power interface is not loose, if the use of redundant power supply, you need to check whether the dual power supply is normal power supply; then observe the appearance of the server, focusing on whether the chassis has abnormal sound, whether the indicator light is abnormally flashing, such as hard disk fault light is always on, power light off, etc., these intuitive signals can be directly directed to the faulty parts.
2, core hardware targeted detection
If there is no abnormality in the appearance inspection, the core hardware can be further detected: through the hardware diagnostic tool that comes with the server, check the running status of the CPU, memory and hard disk, such as using the hardware detection function of the BIOS interface to check whether the memory has poor contact; for the hard disk, You can scan the bad track with the help of the disk detection tool. If the bad track is detected, replace the corresponding hard disk in time and restore the data backup.
Second, how to deal with the failure of the server system?
troubleshooting hardware problems, system-level failures are another high incidence of server failures, involving system crashes, process abnormalities, permission conflicts, and other situations.
1, system start-up fault repair
If the server cannot start normally, you can try to enter the safe mode first to see if it is caused by third-party software or driver conflicts; if the safe mode can enter normally, you can uninstall the recently installed software or updated drivers, and then restart the server. If the safe mode cannot be entered, you can use the system installation media to start, repair the boot partition with the help of system repair tools, or restore the system through backup images.
2, process and permission exception handling
when the server running card or some functions can not be used, open the task manager or system monitoring tool to see if there are abnormal processes occupying too many resources, timely termination of malicious processes or non-responsive background programs; at the same time check the file or directory permissions settings, if insufficient permissions caused by the file can not be read, the program can not run the problem, can adjust the permissions properties of the corresponding file, to ensure that the running user has sufficient operating privileges.
How to solve the server network connection failure?
The core value ofserver is to provide external services, network connection failure will directly lead to business access, such failures need to be investigated layer by layer from the local network to the external link.
1, local network configuration
first check the status of the server's network interface card, check whether the network interface card indicator light flashes normally, execute the ping command through the command line tool, test whether the server's own loopback address is connected, and confirm that the network interface card hardware is faulty; then check whether the Internet Protocol Address, subnet mask, gateway, etc. are configured correctly. If DHCP is automatically obtained, you can try to release and re-acquire the Internet Protocol Address to check whether it is a network interruption caused by IP conflicts.
2, external link and port detection
If the local network configuration is normal, test the ping gateway address and external public IP, troubleshoot whether it is a routing or operator link failure; at the same time, use the port scanning tool to check whether the port that the server provides services to the outside world is normally listening, if the port is not open, It is necessary to add the release rule of the corresponding port in the firewall or security group to ensure that external users can access the server services normally.
four, how to optimize the server performance bottleneck failure?
In addition to sudden failures, the server may experience chronic failures with reduced performance after long-term operation, and such problems need to be optimized from the resource occupation and architecture level.
1, resource utilization optimization
through the system monitoring tool to analyze the server CPU, memory, disk IO real-time occupancy, if the CPU is in a high load state for a long time, you can optimize the code logic of the business program, or upgrade the CPU hardware; if the memory is insufficient, you can close unnecessary background services, or expand the server memory capacity; for the problem of high disk IO, you can migrate frequently read and write data to high-speed solid state drive to improve data reading and writing efficiency.
2, architecture and cache optimization
for servers with high concurrency business scenarios, load balancing architecture can be introduced to disperse traffic to multiple servers to avoid overload of single server resources; at the same time, configure the cache system to store static data accessed at high frequency in the cache, reduce the query request of the server to the back-end database, reduce the running pressure of the server, and improve the overall response speed.
To sum up, server troubleshooting needs to follow the logical sequence from basic to deep, from hardware to software, first eliminate server hardware problems through physical inspection, and then troubleshoot system, network, and performance level failure points in turn. Mastering these troubleshooting and processing methods can help operation and maintenance personnel quickly locate the root cause of server failures, solve problems efficiently, and do regular maintenance and data backup of servers on a daily basis to avoid latent risks in advance, ensure long-term stable operation of servers, and build a solid foundation for enterprise business development.